

Hello folks 👋
In 2026, around half of L&D teams are using AI to make video (52%; Synthesia, AI in L&D Report 2026). The reason is clear: 88% say the main value of AI is time saved on content creation.
The time and cost savings are real and substantial. Before AI, a training video was usually a commissioned job: a production company, a crew, a presenter or actors, and an edit. Agency pricing puts corporate and training video at $1,000 to $10,000 per finished minute (Clutch, 2025). On the AI platforms’ own list prices, a finished minute now costs roughly $1 to $3.
The reduction is easy to trace. The crew is now a monthly platform subscription of about $29. The presenter is AI-generated, and the edit is a prompt. Practitioners report that AI has cut the average production time for a training video by 62%, from 13 days to 5 (Synthesia). In HeyGen’s survey, nearly a third of L&D teams now make more than 21 training videos a month. At pre-AI speeds, that output would have taken around 270 production days: more than a year of one producer’s working time.
And there are signs this is only the start. The tools are multiplying: one directory now tracks 123 AI video generation tools, 108 of them added this year, nearly three-quarters with a free tier (Toolradar, August 2026). They’re diversifying too, from avatar explainers into generated film-style scenes, prompt-built animation, interactive video and AI role-play simulations. And last week Google made its scene generator, Gemini Omni in Google Vids, free to anyone with a Google account.
TL;DR: video production in L&D has been dramatically commoditised, and it’s only getting started. The one question we haven’t stopped to ask is: what’s the impact on learners and learning? Are we helping people learn, or are we just making more video?
In this week’s post, I ask exactly this and share my tips on how to avoid the “magpie effect” and ensure that AI video generation drives learning as well efficiency.
Let’s dive in!
The Current State of AI Video Tools (2026)
As we head towards the end of 2026, AI video tools are multiplying at a rate of knots. One directory now tracks 123 AI video generation tools, 108 of which were added this year (Toolradar, August 2026).
The tools are also diversifying. Two years ago there were two kinds of AI video generation product: a narrated explainer fronted by an avatar (Synthesia, HeyGen, Colossyan) and narrated stock footage (InVideo, Pictory). Now there are seven. The originals are still here, joined by five new flavours:
Generated footage: film-style scenes with spoken dialogue, built from a description rather than a stock library (Google Vids, Veo, Runway, Kling)
Conversational avatars: avatars that listen and reply to the viewer in real time, in a live two-way conversation. HeyGen LiveAvatar does this, and so do Synthesia’s Video Agents, which Synthesia describes as its first step towards two-way video.
Interactive video: branching and quizzes built into the player (Colossyan, Synthesia, HeyGen)
Generated animation: animated video from a document or a single prompt (Vyond Go, Runway, Pika)
Simulations: an AI counterpart for learners to practise conversations and decisions with (Second Nature, Yoodli, Synthesia Roleplay Sessions, Copilot’s Learning Agent)
The tooling menu has never been longer, or cheaper. Last week Google added a free tier to Vids, meaning anyone with a Google account can now generate six AI clips a month, about a minute of footage, without paying anything. This move is part of a broader trend, rather an outlier; nearly three-quarters of the AI video tools now have a generous free tier and low-cost entry point (Toolradar, August 2026).
So generating video for learning content is a bottleneck. But knowing how to use these tools to actually help people learn is.
Every tool on that list can support learning in the hands of someone who knows how to use it. But every one of them defaults to video that does little for it: upload a document, get a narrated summary, publish. That’s information transmission, the job the research says video does least well. Even the simulation tools, which are built for practice, default to the vendor’s stock scenarios and an AI score nobody has validated. The tools have changed. The defaults haven’t.
To understand why the defaults matter, and what to do instead, we need to look at what the research says video actually does for a learner, and what it doesn’t.
The Science of Video-Based Learning 101
L&D loves video. We tend to assume it’s the premium format: more engaging than text, more dynamic than slides, more likely to be opened than a PDF.
It’s easy to see why. Video looks like effort and investment, so stakeholders read it as quality. It gives us metrics that look like success, such as views, completion and watch time. And it feels easier to learn from. Research shows that learners rate video as less demanding than text and come away feeling they’ve learned more (Salomon, 1984; Paik & Schraw, 2013).
That last point is also the trickest. Feeling that you’ve learned isn’t the same as having actually learned. So if the goal is learner satisfaction, video wins. But if your goal is measurable and substantive learning, the picture is very different.
Over forty years of research confirmed that video-based learning has one pedagogical benefit that text on a page can’t give a learner: a model of how something unfolds in time.
To do something yourself, whether it’s a procedure or a conversation, you need more than the information as a rule; you need a picture of what doing it looks like: the order, the timing, what changes and when. Learners build that picture by watching someone do it and rehearsing it in their heads (Bandura’s observational learning). A page gives you the rule, but it can’t give you the picture in the way that a video can.
So video helps most when the learner has a performance to reproduce. Here are three related use cases for video-based learning and the data on their impact:
Completing a task in a fixed order. Watching a task being done from the operator’s viewpoint lets the learner rehearse the movement before doing it (Fiorella et al., 2017). Dynamic visuals beat static ones by d = 1.06 for this kind of content (Höffler & Leutner, 2007).
Developing a behaviour in a live interaction. To have any hope of changing their behaviour, a learner has to see the behaviour in action, not read about it on the page. Behaviour-modelling training shows the behaviour done badly and well, spells out the rules for great, then adds practice and feedback. This method is backed by ~120 studies which demonstrate real, measurable effect on learner behaviour and performance over time (Taylor, Russ-Eft & Chan, 2005).
Identifying the difference between right and nearly-right. What differentiates great from not great is most often an action, not a word. Comparing near-identical cases by watching the differences in action trains learners to notice the feature that matters better than explanations (Schwartz & Bransford, 1998; Kellman et al., 2010).
So the TL;DR is that video can be a very effective mode of delivery for learning, but only when it’s used for the right kind of goal and in the right way.
Correspondingly, there are also ways we can use video which either have no impact on learning or - worst case scenario - negatively impact learner engagement and learning outcomes. Here are two common examples of the latter:
Example 1: The wrong kind of goal: information the learner needs to keep.
When the content is a concept, a rule or a definition, nothing unfolds, so there’s nothing to model. Worse, the learner loses what a page gives them for free: the ability to go back.
Once the clip moves on, it’s gone (Leahy & Sweller, 2011). Across 61 studies comparing animated with static graphics, the advantage was small (g ≈ 0.23; Berney & Bétrancourt, 2016). This is where the satisfaction trap bites hardest: the explainer feels easy, so learners think they’ve got it.
Example 2: The wrong way: watching without doing.
Even for the right kind of goal, a video only becomes learning when the learner does something with it. Across 105 randomised trials in higher education, most of them in health sciences, video added to active teaching gave g = 0.80; video swapped in for active teaching gave g = 0.28 (Noetel et al., 2021).
Asking questions between video segments took final test scores from 68% to 90% (Szpunar, Khan & Schacter, 2013). Reviewing a recording of your own performance against a standard improved professionals’ interaction skills by 0.40 SD (Fukkink et al., 2011). The pattern is consistent: the video content is never the intervention. The question, the practice and the feedback are.
How AI Video Tools Work
Now, let’s compare the science of video-based learning to what the AI video tools are built to do.
Open almost any of them and the first thing on offer is a document to upload or a script to fill in. The output is a narrated summary: information the learner can’t go back to, with no performance to model and nothing to do. In other words, the wrong goal, used the wrong way.
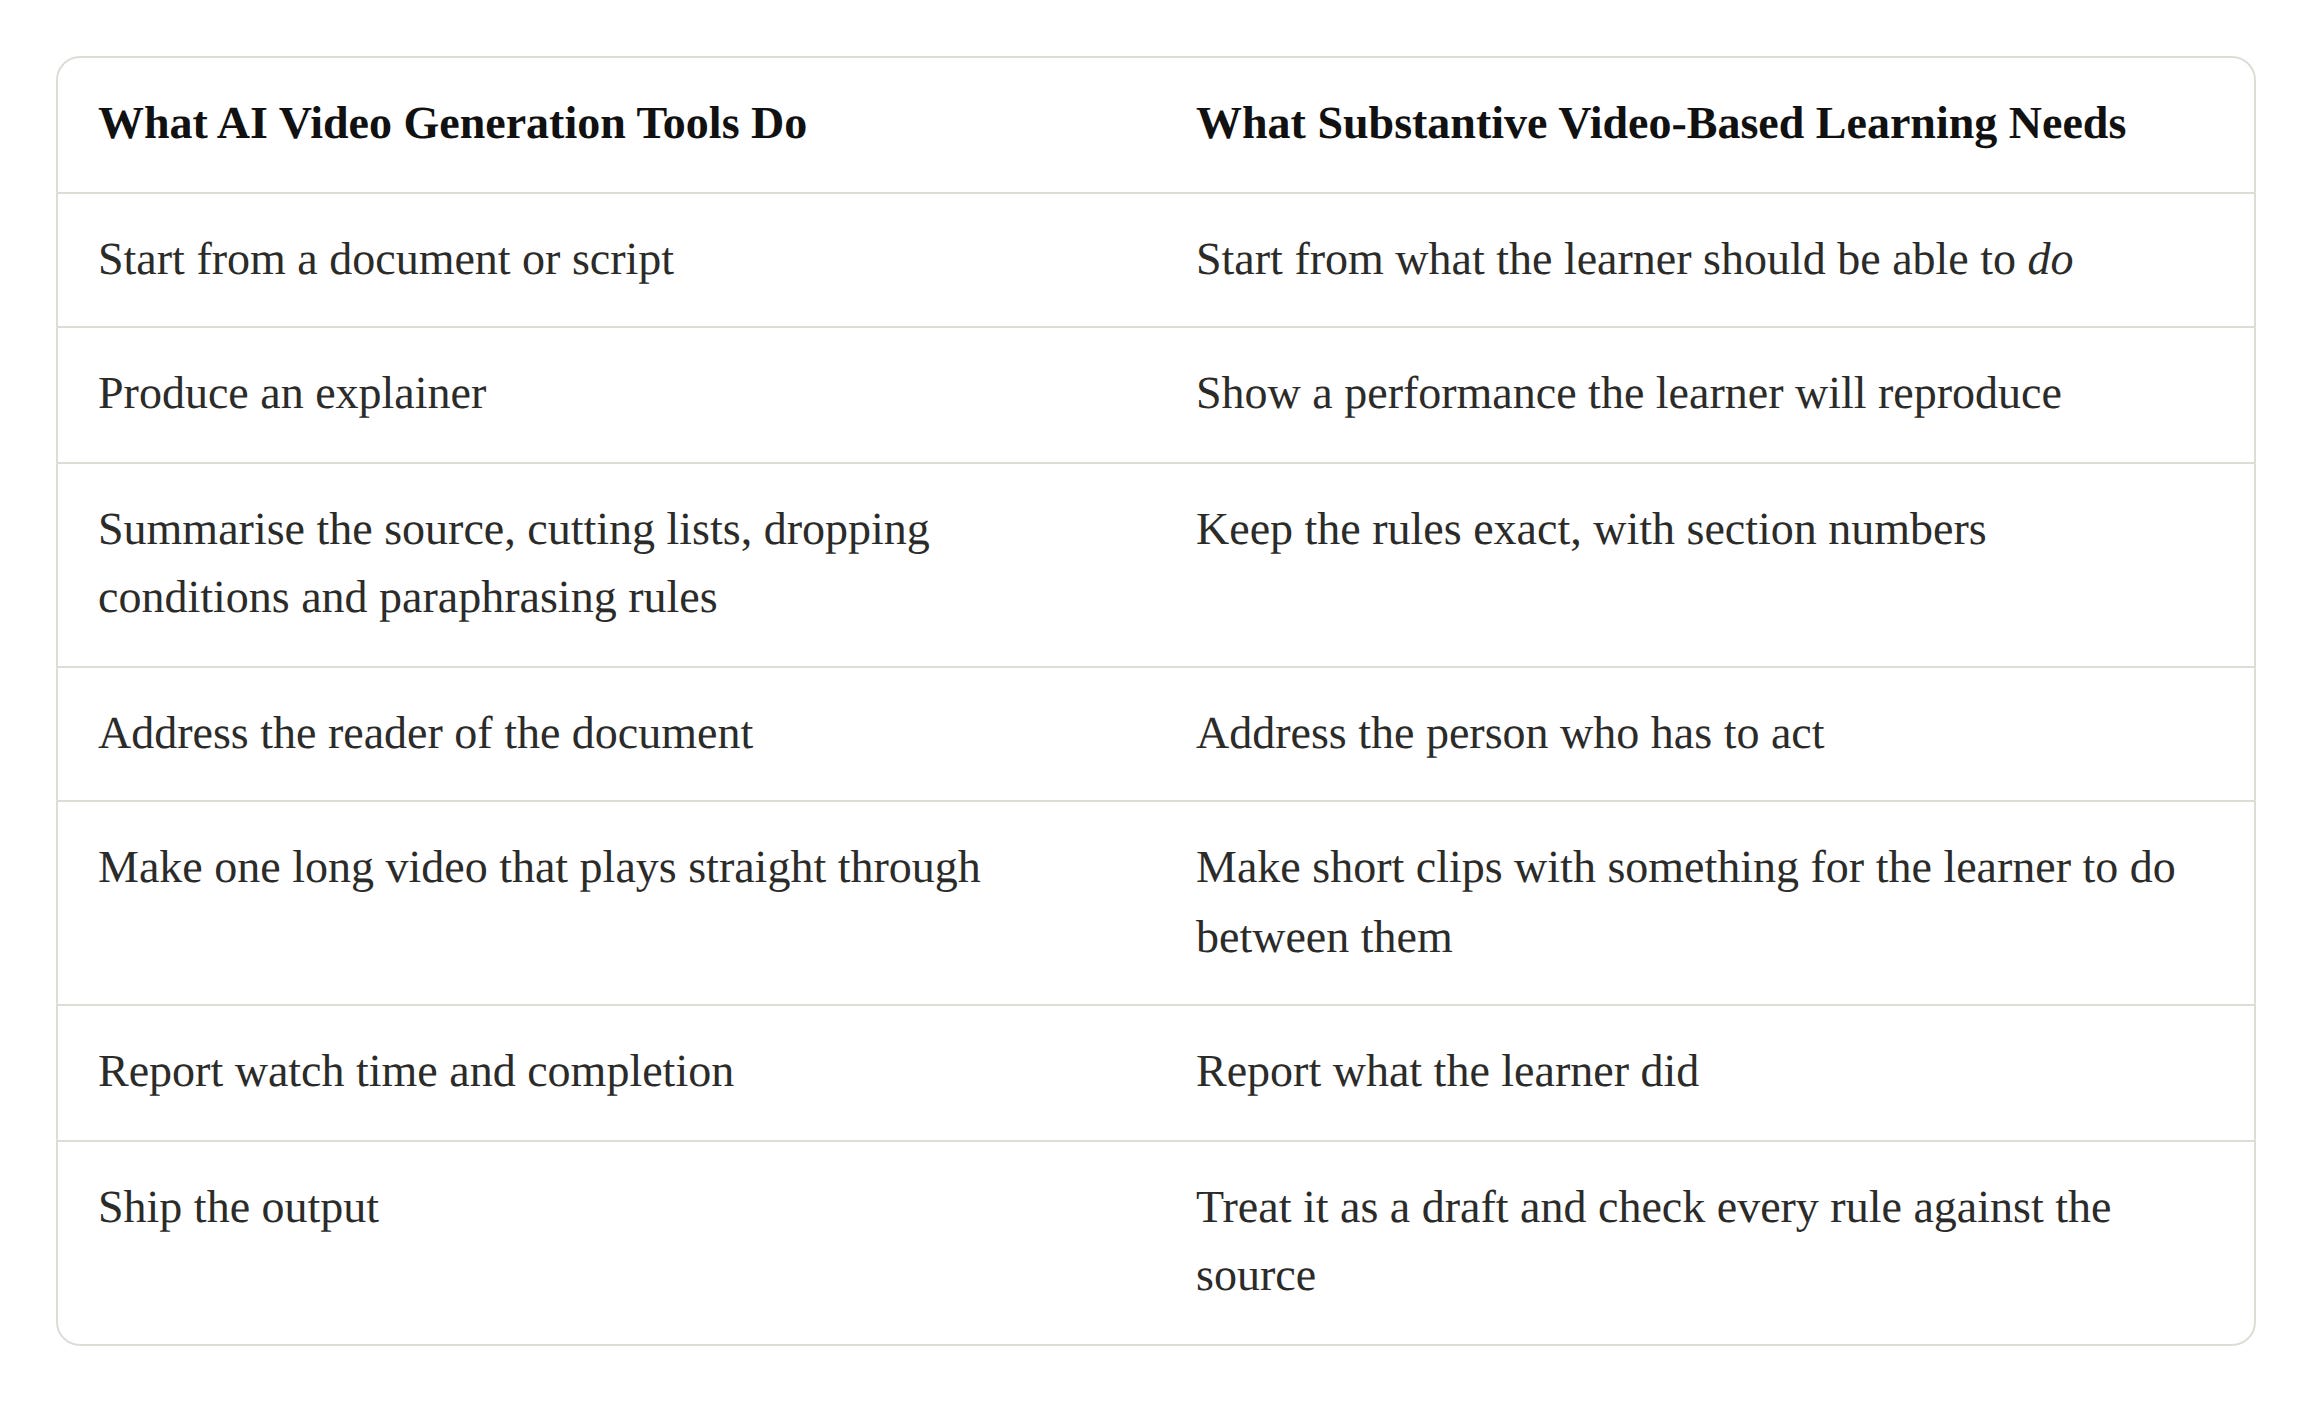
What’s noticeable is that every AI video tool now offers the same default: upload a document, get a narrated video. This isn’t the only thing that these tools do, but it’s the first, default option on the screen when you open them, and the fastest route to something that looks finished.
To see what it produces, I ran that default workflow on a real document: a publicly available 2013 GSK procedure for reporting misconduct. It’s exactly the kind of policy L&D teams turn into compliance training every week, and exactly the sort of doc they’d upload to generate a video.
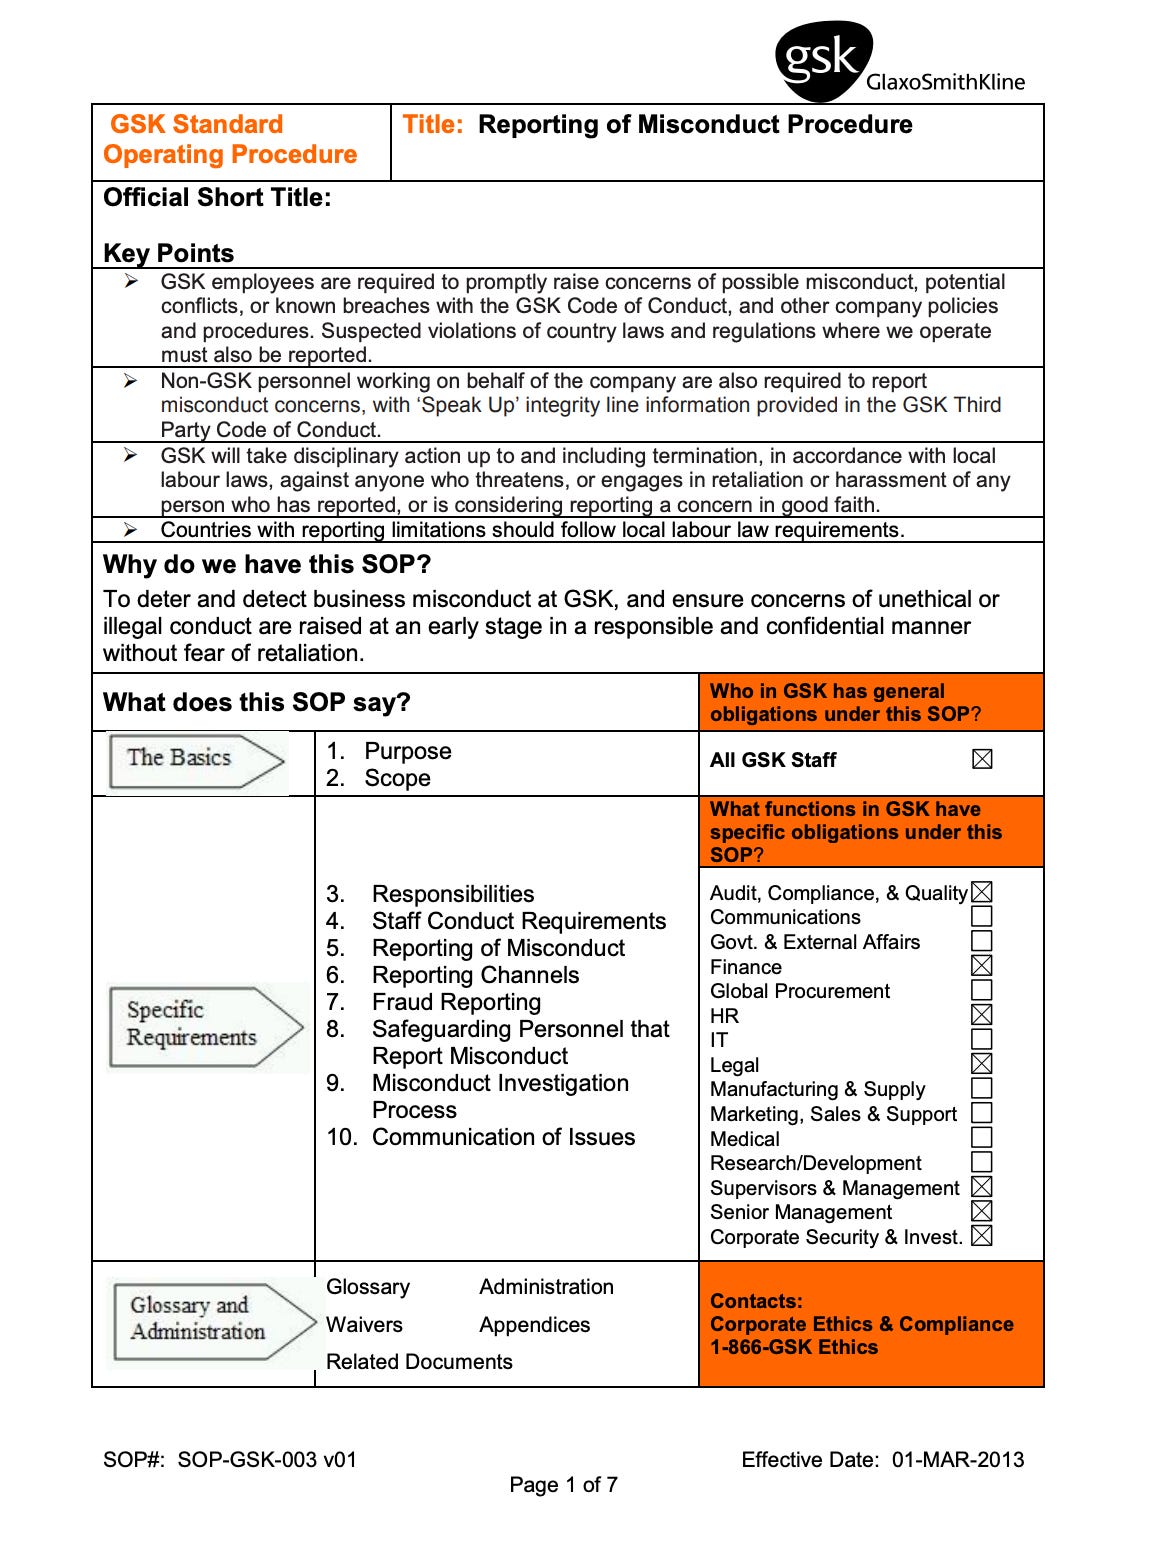
I ran the doc two ways:
First, I let the tool decide. I uploaded the procedure, chose Docs to video, and pressed Create. The only input was the document. The tool chose what to keep, what to cut, who the film was for and what it should say.
Then I decided. Before opening the tool, I made the decisions the default had made for me:
Who is the learner? The manager receiving a report, not the employee making one.
What should they be able to do? Respond to a report in line with the procedure: stop, listen, and take it forward rather than dismissing it.
What would doing it badly look like? Specific, visible behaviours a learner could point at and name.
The default outputs failed in five ways, each of which maps onto a well-documented way that learning goes wrong:
1. AI rewrote the rules, and made the rewrite convincing. The finished film turned “any executive directly senior to the person making the report” into “any senior executive you trust”. It turned “believe may be taking place” into “if you see it”. It added a “zero tolerance” line that appears nowhere in the document. A second tool, which quoted the source on screen and preserved far more of it, still invented a rule about fraud reporting that isn’t there.
Why this matters: video feels easy, and learners overestimate what they’ve learned from it (Salomon, 1984; Paik & Schraw, 2013). So a wrong rule delivered fluently doesn’t just fail to teach; it teaches the wrong thing with confidence. And misinformation is stubborn: once people have taken in a false claim, a later correction rarely removes it completely (Lewandowsky et al., 2012). An error in a compliance video isn’t a typo you fix in version two. It’s a belief you then have to unteach.
2. AI cut what didn’t fit. Six of the ten reportable categories disappeared. So did half of the escalation routes, and one of the two conditions for going above your manager (”or if the concern persists”). Lists were cut from the bottom.
Why this matters: what got cut is exactly what people get wrong in real life: the edge cases and the “unless” clauses. A summary keeps the gist and drops the conditions, but in compliance the conditions are the point.
In the free version of Google Vids, for example, video length defaults to 10 seconds which requires a lot of editing when the source is a 7-page doc:
3. AI spoke to the wrong person. The document addresses three audiences: employees, managers, and the functions that investigate. The film collapsed them into one, “you”, the employee. Every duty the procedure places on managers vanished.
Why this matters: behaviour change starts from who has to act and what they have to do (Taylor, Russ-Eft & Chan, 2005). A manager who watched this film would learn nothing about the moment the procedure cares about most: what to do when someone reports to them.
4. AI gave the answer before the learner could think. When I asked for a “What went wrong?” moment, the tool put the question and three answers on the same frame. The answers were generic, too: “dismissive body language”, “lack of empathy”. None of them came from the procedure.
Why this matters: the learning happens in the gap between question and answer. Questions between video segments took final test scores from 68% to 90% because learners had to retrieve the answer (Szpunar, Khan & Schacter, 2013). Predictions help most when they turn out to be wrong (Brod, Hasselhorn & Bunge, 2018). A question answered on the same frame isn’t a question any more; it’s a caption.
5. AI ran long, and added things nobody asked for. One version ran to over nine minutes of continuous narration. Another added a company logo, and on-screen labels (”Listen / Reassure / Escalate”) that I didn’t ask for and the procedure doesn’t use.
Why this matters: in an analysis of 6.9 million edX video sessions, engagement dropped sharply after about six minutes (Guo, Kim & Rubin, 2014). Once a clip moves on, what it said is gone (Leahy & Sweller, 2011). Material that isn’t in the source competes for attention and reduces learning (Mayer’s coherence principle). Labels made up by the model also look authoritative, and they aren’t from the procedure.
The key finding here is that the risk in AI video generation tools lies in their defaults. AI video generation tools don’t produce bad video; they produce good-looking video that is pedagogically flawed: incomplete, incorrect, aimed at the wrong person, and built to be watched rather than used.
That last flaw matters most, because it is invisible to most of the people who watch it — including learners. Video earns its place in the learning experience when it gives learners a model of a performance they’ll have to reproduce: a behaviour, a sequence, the difference between right and nearly-right. Even then, watching is only the first step. The learning comes from what the learner does with what they’ve watched: predicting what happens next, spotting what went wrong, answering a question before the next clip plays, practising it themselves and getting feedback.
That’s why video added to active teaching gave g = 0.80, while video swapped in for it gave g = 0.28 (Noetel et al., 2021). It’s also why a question between segments took final scores from 68% to 90% (Szpunar, Khan & Schacter, 2013). And it’s why an answer on the same frame as the question wipes out the benefit.
The default settings of these tools turn all of that around. They take information that video adds the least to, give the learner nothing to model, and ask nothing of them except to keep watching. Then, because video feels easy, it leaves the learner believing they’ve learned more than they have.
So the default settings of these tools fail. But the defaults are only the first option on the screen, not the only thing these tools can do. Which raises the question this post is really about: if we take the decisions back, and if these tools are used by people who understand how people learn, can the same tools make video that the research says actually helps people learn?
Can AI Video Tools Deliver Substantive Learning?
The question we need to ask of any AI video generation tool isn’t “what can it make?” It’s “which proven learning strategy can I deliver with it, and what goes wrong if I leave it on its default settings?”
So the question to ask of any AI video tool isn’t “what can it make?” It’s “which proven learning strategy can I deliver with it, and what goes wrong if I leave it on its default settings?”
Six instructional strategies use video in the way the research supports. Each one gives learners something to watch and something to do.
Six Strategies to Use Video For
1. Behaviour modelling
What it is: learners see a behaviour done badly, then done well, with the rules that separate the two spelled out. Then they practise it themselves.
Use it when: learners need to do something in a live situation (give feedback, receive a complaint, handle a report) and haven’t seen it done well.
Why it works: you can’t reproduce a standard you’ve never seen, and the rules tell learners which parts of the picture matter. Across 117 studies, behaviour-modelling training improved skills and job behaviour, and the effects held or grew over time. It worked best with good and bad models, explicit rules, and practice on the learner’s own cases (Taylor, Russ-Eft & Chan, 2005).
2. Contrasting cases
What it is: four near-identical versions of the same scene, each differing in one thing. Learners work out which one is right and what’s wrong with the others.
Use it when: learners know the rule but miss the near-misses. They say the right words with the wrong action, or do the right thing in the wrong place.
Why it works: noticing is a skill, and comparison trains it better than explanation. Comparing cases before the explanation means learners have already spotted the thing the explanation is about (Schwartz & Bransford, 1998; Kellman et al., 2010).
3. Erroneous examples
What it is: a correct sequence with one visible mistake in it. Learners find the mistake and say why it’s wrong.
Use it when: learners already know the procedure and need to catch errors in situations they haven’t seen. Use it in week two, not week one.
Why it works: finding a mistake means running the procedure in your head and checking against it, which is exactly the check learners need to make on the job. But it only helps learners who already know the procedure. For novices, it gets in the way (Große & Renkl, 2007).
4. Predict, then see
What it is: the scene stops at the decision point. Learners say what should happen next, then see what does.
Use it when: the rule and the learner’s instinct disagree, and for any sequence longer than one clip.
Why it works: committing to an answer before seeing it makes the answer stick, especially when the prediction was wrong (Brod, Hasselhorn & Bunge, 2018). Questions between video segments raised final test scores from 68% to 90% (Szpunar, Khan & Schacter, 2013).
5. First-person demonstration
What it is: a physical or software task filmed from the operator’s own viewpoint, one step per clip, in the right order.
Use it when: learners need to carry out a task in a fixed sequence: a pre-use check, a system workflow, a technique.
Why it works: learners rehearse the movement from where their own hands will be. This is where video’s advantage over static images is largest (d = 1.06; Höffler & Leutner, 2007). First-person footage beat third-person (Fiorella et al., 2017). Keep the presenter out of shot: a visible instructor made procedural video harder to follow (Turan & Kasneci, 2026).
6. Practice with feedback
What it is: learners do the behaviour themselves with a counterpart who responds. They’re recorded, they review the recording against a standard, and they get feedback from a person.
Use it when: learners can already do the behaviour, and you need them to do it repeatedly on realistic cases, with evidence that they can.
Why it works: a model gives learners a picture of what good looks like. Practice under pressure is what makes them able to act on it. A recording shows them what they couldn’t see while doing it, and a coach tells them what to change.
An AI practice partner raised medical students’ self-rated skills almost as much as a trained actor, at half the cost (Tyrrell et al., 2025; n = 396).
Five minutes of directive coaching between attempts beat reflection alone across five studies (Cohen et al., 2020, 2024).
Coaching on a learner’s own recording improved surgical skill by SMD 0.71 across 15 trials (Anderson et al., 2025).
Which AI tools can (and can’t) deliver these strategies?
Now, we need to map the strategies to the tools. None of the tools do any of this by default: each one needs an expert user who knows:
The decisions to make before opening the tool: who the learner is, what they need to be able to do, which behaviour to show, which rules apply, and what the learner does with the clip afterwards.
How to direct the tool to carry those decisions out. Directing the tool means spelling out everything you need and checking everything it gives back. In practice:
Write the scene, not the topic. Describe who’s in the room, where they are, every action and every line of dialogue, in order. Anything you leave out, the tool fills in for you. That’s how a “zero tolerance” line ends up in a policy that never said it.
Keep the characters consistent. Write one line describing the setting and the people (”open-plan office; employee, 30s, light blue shirt; manager, 40s, grey polo, at a laptop”) and paste it at the start of every prompt, so the same people appear in every clip.
Change one thing at a time. Use Edit, not a new prompt, and say “same scene, same people, change only this”. Contrasting cases depend on everything else staying the same.
Build sequences, not long clips. A generated clip lasts about ten seconds, so plan one behaviour per clip. Use Extend for what happens next, and put the question between clips in your LMS, because the generator can’t pause.
Tell it what not to do. “No narration.” “Do not show the response.” “Do not signal that anything is wrong.” Left to themselves, the tools explain, resolve and reassure, which is exactly what spoils a prediction or an erroneous example.
Check every clip against your rules. Watch with captions on and count the behaviours you asked for. Compare every line of dialogue with the source. Regenerate anything that’s missing, softened or invented. A clip that looks right isn’t necessarily right.
Know when not to generate. For a real procedure, record it and use AI only to check, label and edit the footage. For information learners need to keep, use a page.
The table below shows how this could play out in practice:
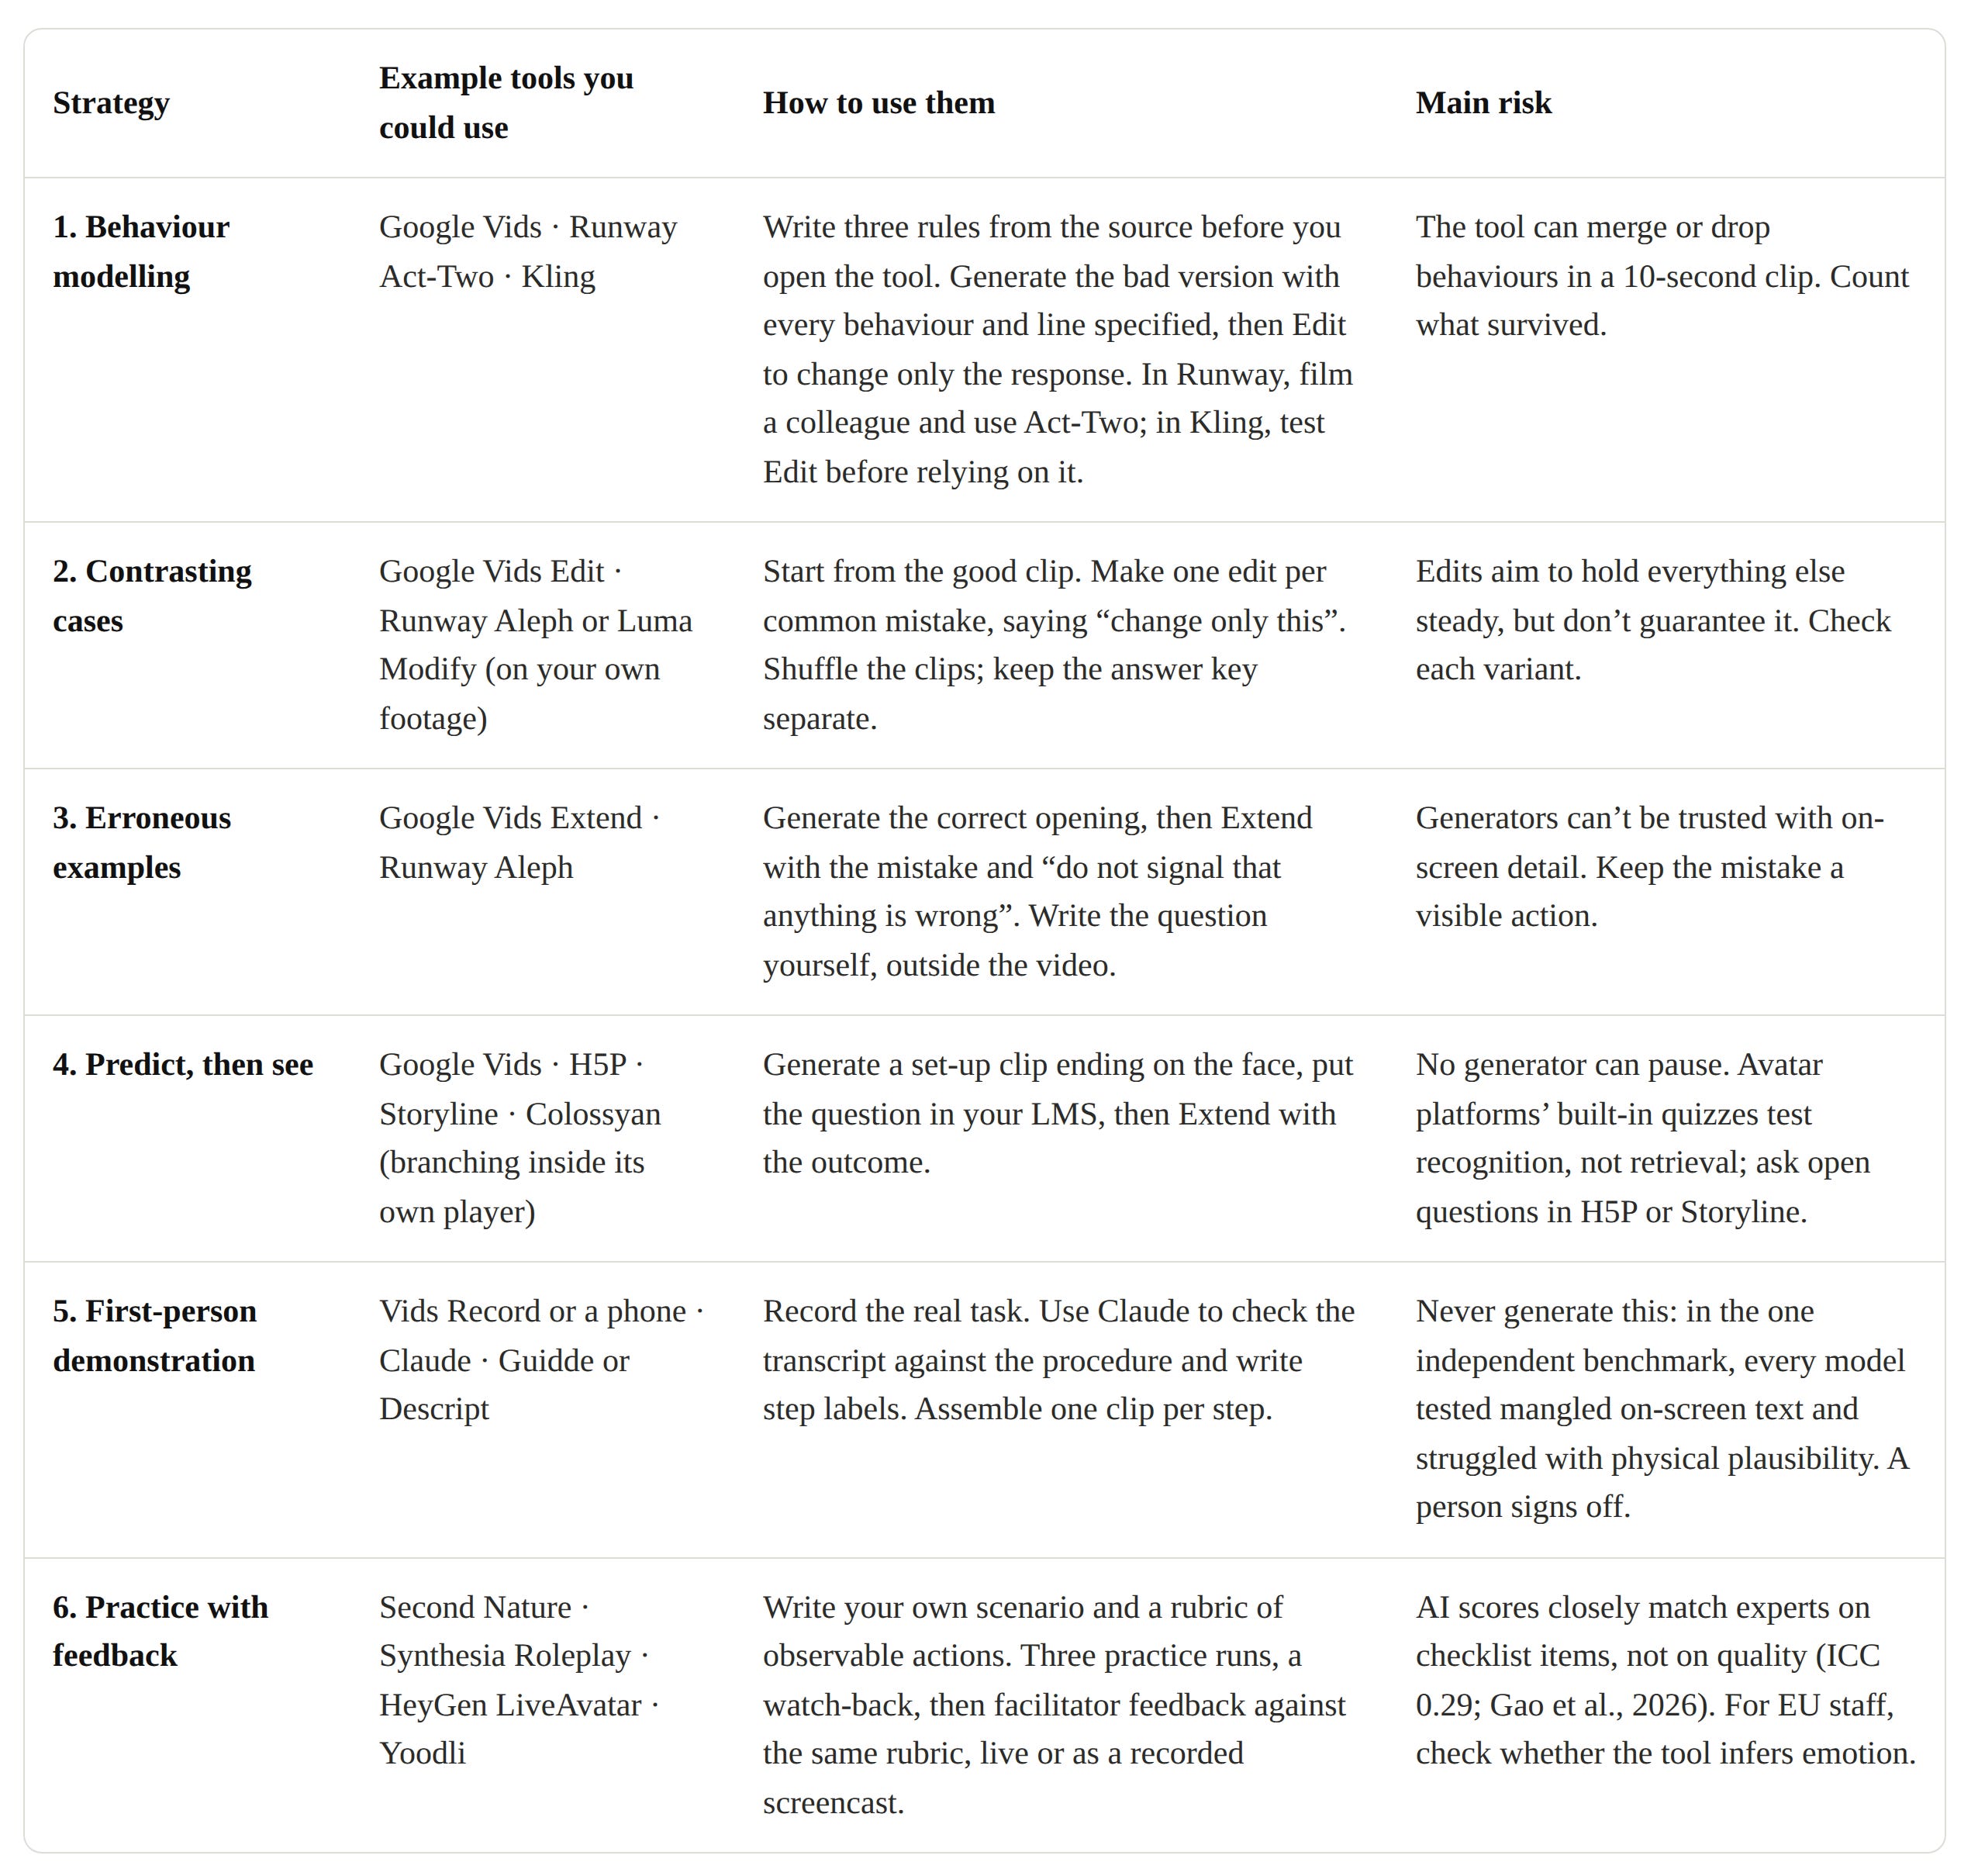
Notice that there are a number of AI video generation tools that don’t appear in this table:
Document-to-video tools (Notebook, Docs to video, Doc2Video) don’t enable the user to specify a person, a line or a behaviour, so they can’t deliver strategies 1–4.
Presenter avatars which can read a script exactly but can’t show conduct
Generated animation has one use case with some limited evidence behind it: showing a concept build as it’s explained (Fiorella & Mayer, 2016). For everything else, it’s just an explainer with more motion and should be a document instead.
Conclusion: AI Video Tools Need You
AI has made video generation for learning content almost free. A finished minute that cost thousands of punds two years ago now costs a few, the menu of tools has never been longer, and as of last week the most capable scene generator on the market costs nothing at all. Most L&D teams already use these tools, and almost all of them say they do it to save time.
This is the latest and most prolific chapter of the magpie effect at work in L&D: an abundance of shiny new tools, each of which will turn a document into a polished film in a couple of minutes. But as my rapid tests show, that polished film is the version of AI video that does least for learning: it’s incomplete, sometimes wrong, aimed at the wrong person, and built for watching rather than doing.
The research is clear about what video is for. It earns its place when it gives learners a model of a performance they have to reproduce, and when the learner does something with what they’ve watched: compares, predicts, spots the mistake, practises, gets feedback. Used that way, video has decades of evidence behind it. AI tools can now produce that kind of video quickly and cheaply. But none of them does it by default.
As is always the case with AI, what makes the difference isn’t the tool — it’s the person using it, and what they know about their domain. When it comes to AI video generation tools, the user who needs to know things like:
what the learner should be able to do once they’ve watched the video
which strategy will get them there, and whether video is the right medium at all
which behaviour to show, which mistake to include, and which rules apply
how to direct the tool to produce exactly that, and nothing else
how to check what comes back against the source
None of that comes in the box: it’s deep the expertise of knowing how people learn and designing for it that L&D has always provided. What has changed is the cost of skipping this stage. Bad video used to be expensive enough that someone asked whether it was worth making. Thanks to AI, it’s now it’s cheap enough that nobody has to ask before it’s generated and published.
The tools make video cheaper, but they don’t make it effective. That part, as ever, is down to us.
Happy innovating!
Phil 👋
PS: PS: If you want to learn how to get real value from AI, apply for a place on my AI bootcamp for L&D.
I understand this piece focuses on the learning benefits and how to design towards realizing these benefits, but I’m curious what your research or conversations with with L&D teams indicates around content creation copyright and IP protection. At my organization we are blocked from adopting tools like Synthesia (even though we really enjoyed the build experience in testing) because of concerns of how protectable our AI-generated would be. How are folks thinking about and approaching these kinds of concerns?